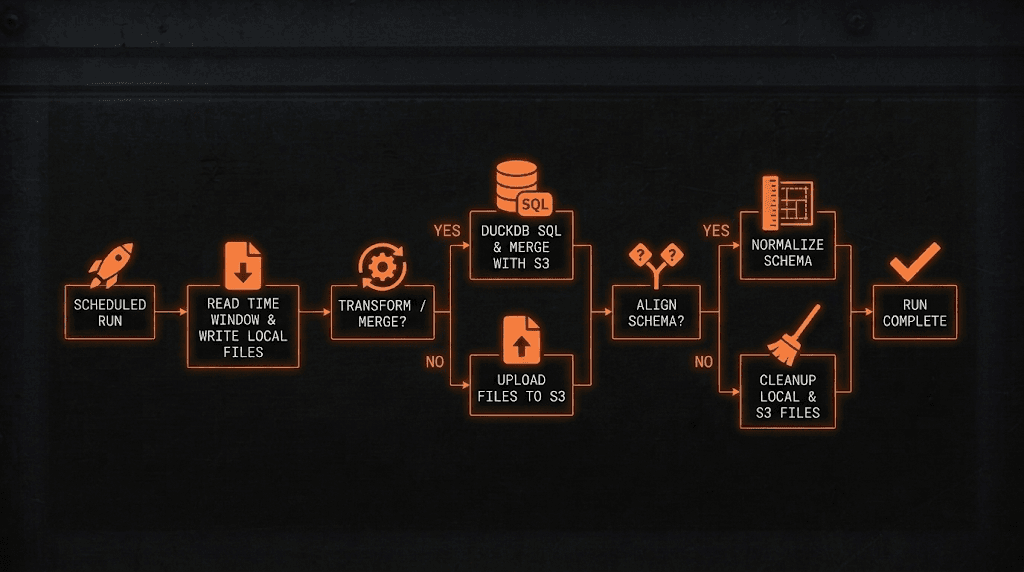
Airflow ETL platform on AWS
Problem
Data extractions mostly did not exist. The rest were one-off scripts and manual runs.
Approach
22 Apache Airflow DAGs on EC2 extract from PostgreSQL and MongoDB, process with Polars and DuckDB, and write Parquet to S3. Six DAGs run every 15 minutes (about 576 runs a day, 1–2 minutes each), six run nightly, and ten run monthly (up to 10 hours). Loads range from hundreds of MB to dozens of GB.
Outcome
Reliable automated pipelines feed 1 live product and are designed to scale to more. A follow-up MVP moves processing to Apache Spark toward an S3 Apache Iceberg lakehouse.